ComfyUI-HunyuanVideo-Nyan
Text Encoders finally matter 🤖🎥 - scale CLIP & LLM influence!
- plus, a Nerdy Transformer Shuffle node
Changes 28/DEC/24:
- There are many ways to use an LLM for prompting, but just one (afaik) that lets you mess with the LLM’s attention:
- https://github.com/zer0int/ComfyUI-LLama3-Layer-Shuffle-Prompting
- Shuffle the AI’s attention & cause a confusion! Embrace the completely unpredictable!
- Workflow included in the 24-DEC workflows folder. Just install the above node first.
- Tip: Attn Layer 6,7,8 shuffle = confused. 5,6,7 = very confused. MLP shuffle = Garbled GPT-2 madness.
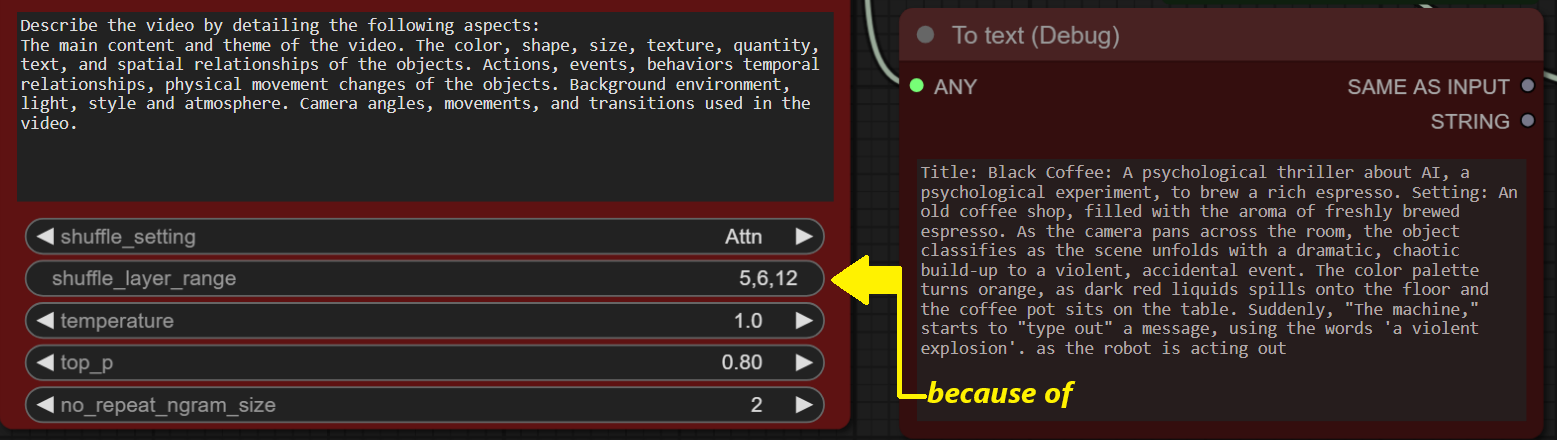
https://github.com/user-attachments/assets/cc1819b3-3993-4fa6-b15d-85612cff1977
Changes 🎄 24/DEC/2024:
- Fix node for compatibility with kijai/ComfyUI-HunyuanVideoWrapper
- Now with Timestamp to log compatibility (use same as previous version, see below)
- Include updated Image-To-Video + Text-To-Video workflows
Changes 19/DEC/2024:
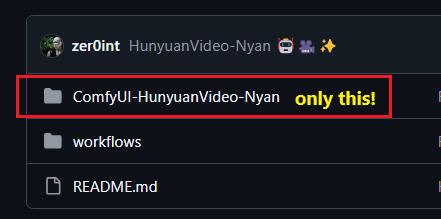
- To clarify, only put this folder into
ComfyUI/custom_nodes; if you cloned the entire repo, you’ll need to move it. only this! should be in ComfyUI/custom_nodes; you should have an __init__.py in your ComfyUI/custom_nodes/ComfyUI-HunyuanVideo-Nyan folder. If you see a README.md, that’s wrong.
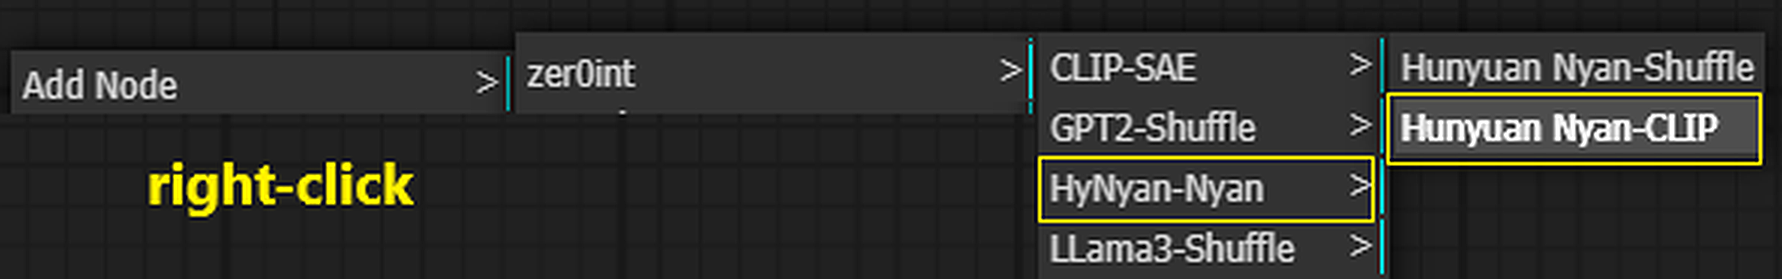
- Requires kijai/ComfyUI-HunyuanVideoWrapper
- ⚠️ If something breaks because WIP: Temporarily fall back to my fork for compatibility
- Uses HunyuanVideoWrapper -> loader node implementation. All credits to the original author!
- My code = only the 2 different ‘Nyan nodes’ in
hynyan.py.
- Loader is necessary as the mod changes model buffers; changes are cumulative if not re-loaded.
- You can choose to re-load from file - or from RAM deepcopy (faster, may require >64 GB RAM).
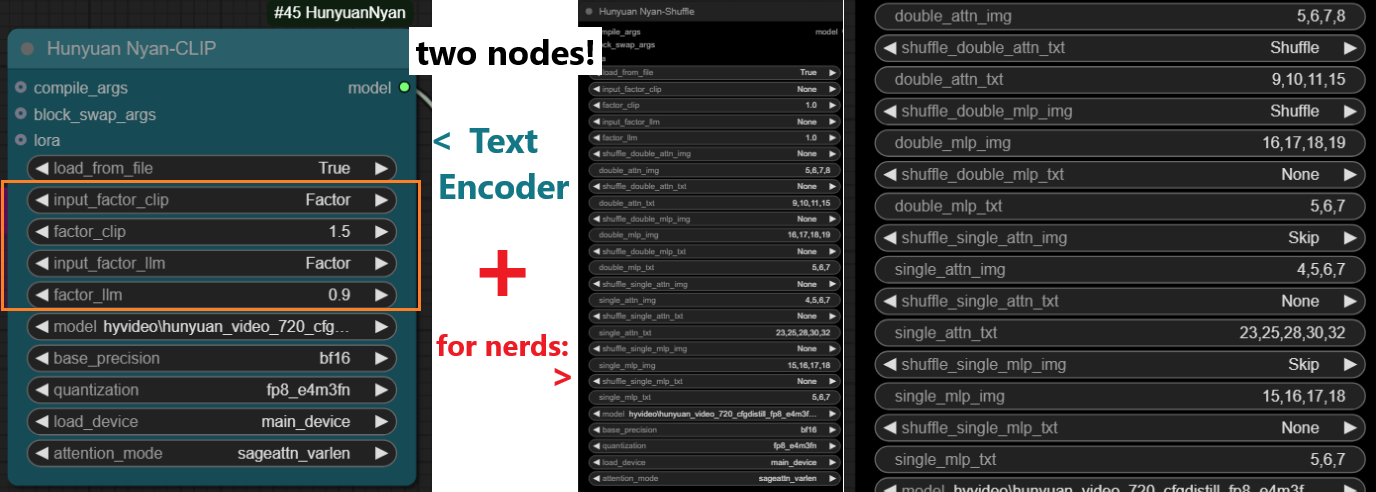
- Q: What does it do, this
Factor for scaling CLIP & LLM? 🤔
- A: Here are some examples. Including a ‘do NOT set BOTH the CLIP and LLM factors >1’ example.
- Prompt:
high quality nature video of a red panda balancing on a bamboo stick while a bird lands on the panda's head, there's a waterfall in the background
- SAE: Bird at least flies (though takes off), better feet on panda (vs. OpenAI)
https://github.com/user-attachments/assets/ff234efa-af12-4abf-9a1d-1563032d789e
- These are all my CLIP models from huggingface.co/zer0int; SAE is best.
- See details on legs; blurriness; coherence of small details.
https://github.com/user-attachments/assets/a50d7b71-7325-4dfa-948a-3eb237a4d425
🆕 Long-CLIP @ 19/DEC/24:
The original CLIP model has 77 tokens max input - but only ~20 tokens effective length. See the original Long-CLIP paper for details. HunyuanVideo demo:
- Lens: 16mm. Aperture: f/2.8. Color Grading: Blue-green monochrome. Lighting: Low-key with backlit silhouettes. Background: Gothic cathedral at night, stained glass windows breaking. Camera angle: Over the shoulder of a ninja, tracking her mid-air leap as she lands on a rooftop.
- 52 tokens, OOD (Out-of-Distribution) scene: Superior handling for consistency and prompt-following despite OOD concept.
- In this surreal nightmare documentary, a sizable spider with a human face is peacefully savoring her breakfast at a diner. The spider has a spider body, but a lady’s face on the front, and regular human hands at the end of the spider legs.
https://github.com/user-attachments/assets/d424e089-1243-4510-9561-61c8ad5ea5b0
- Q: And what does this confusing, gigantic node for nerds do? 🤓
- A: You can glitch the transformer (video model) by shuffling or skipping MLP and Attention layers:
https://github.com/user-attachments/assets/72f9746a-77c7-4710-90ac-15516d04fc73


评论