Next-Gen Data Discovery and Data Observability Platform
Website •
LinkedIn •
Slack •
Documentation •
Blog •
Demo
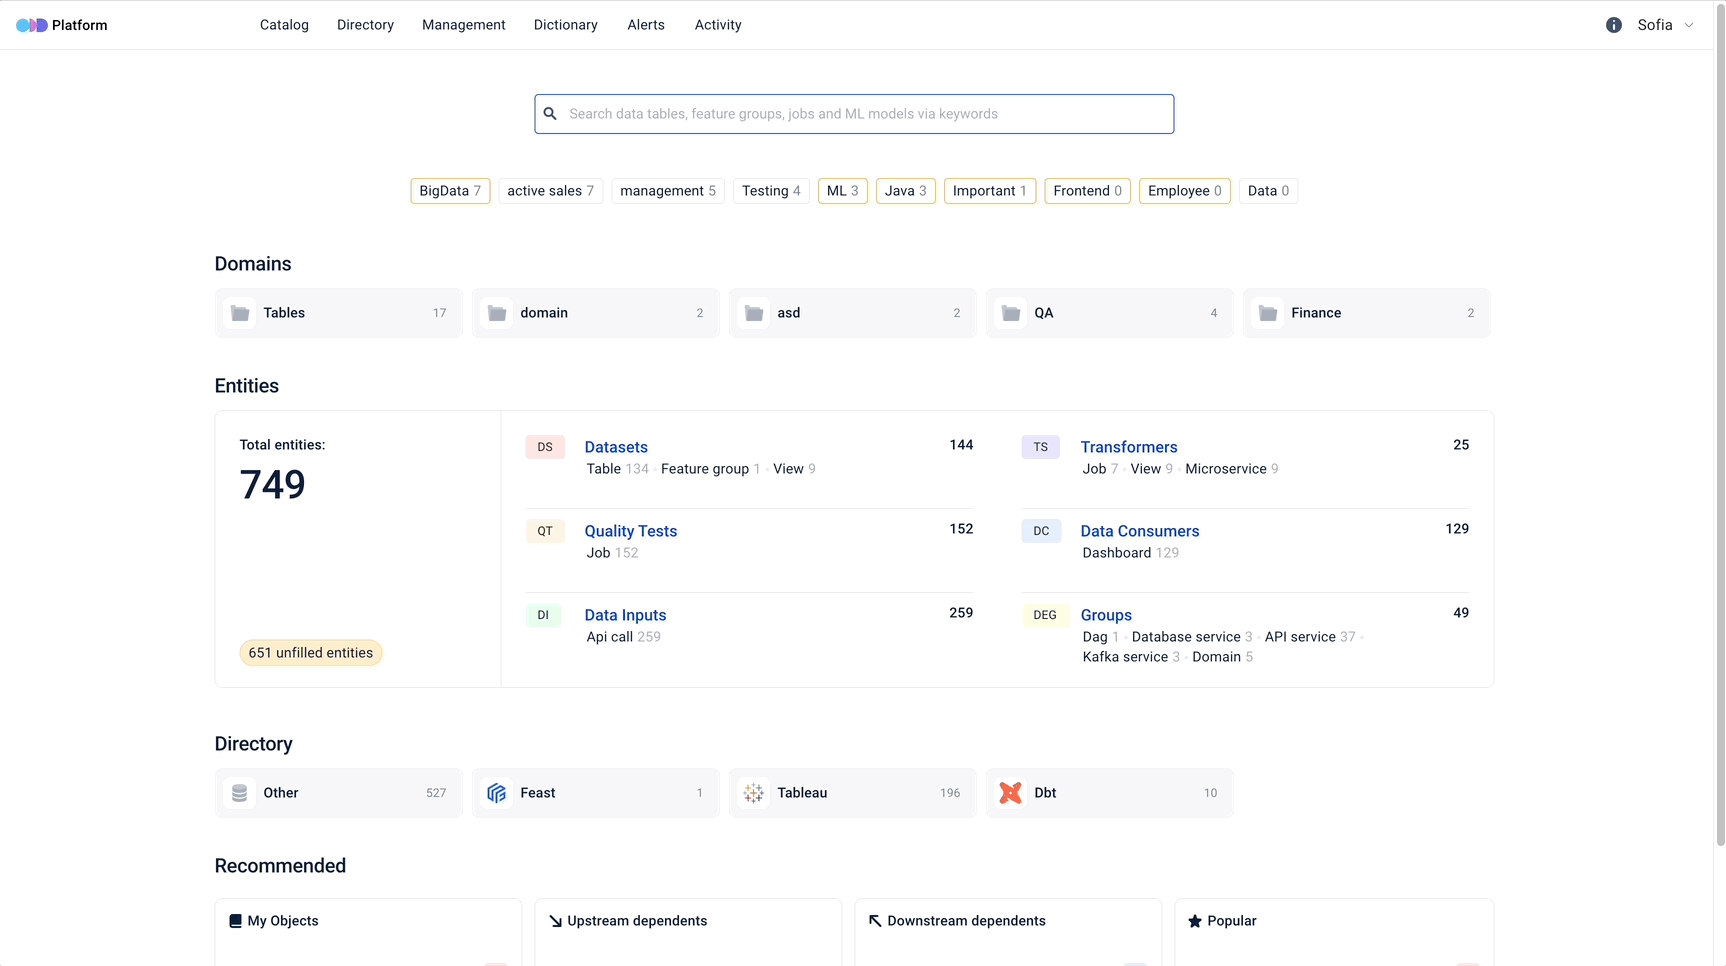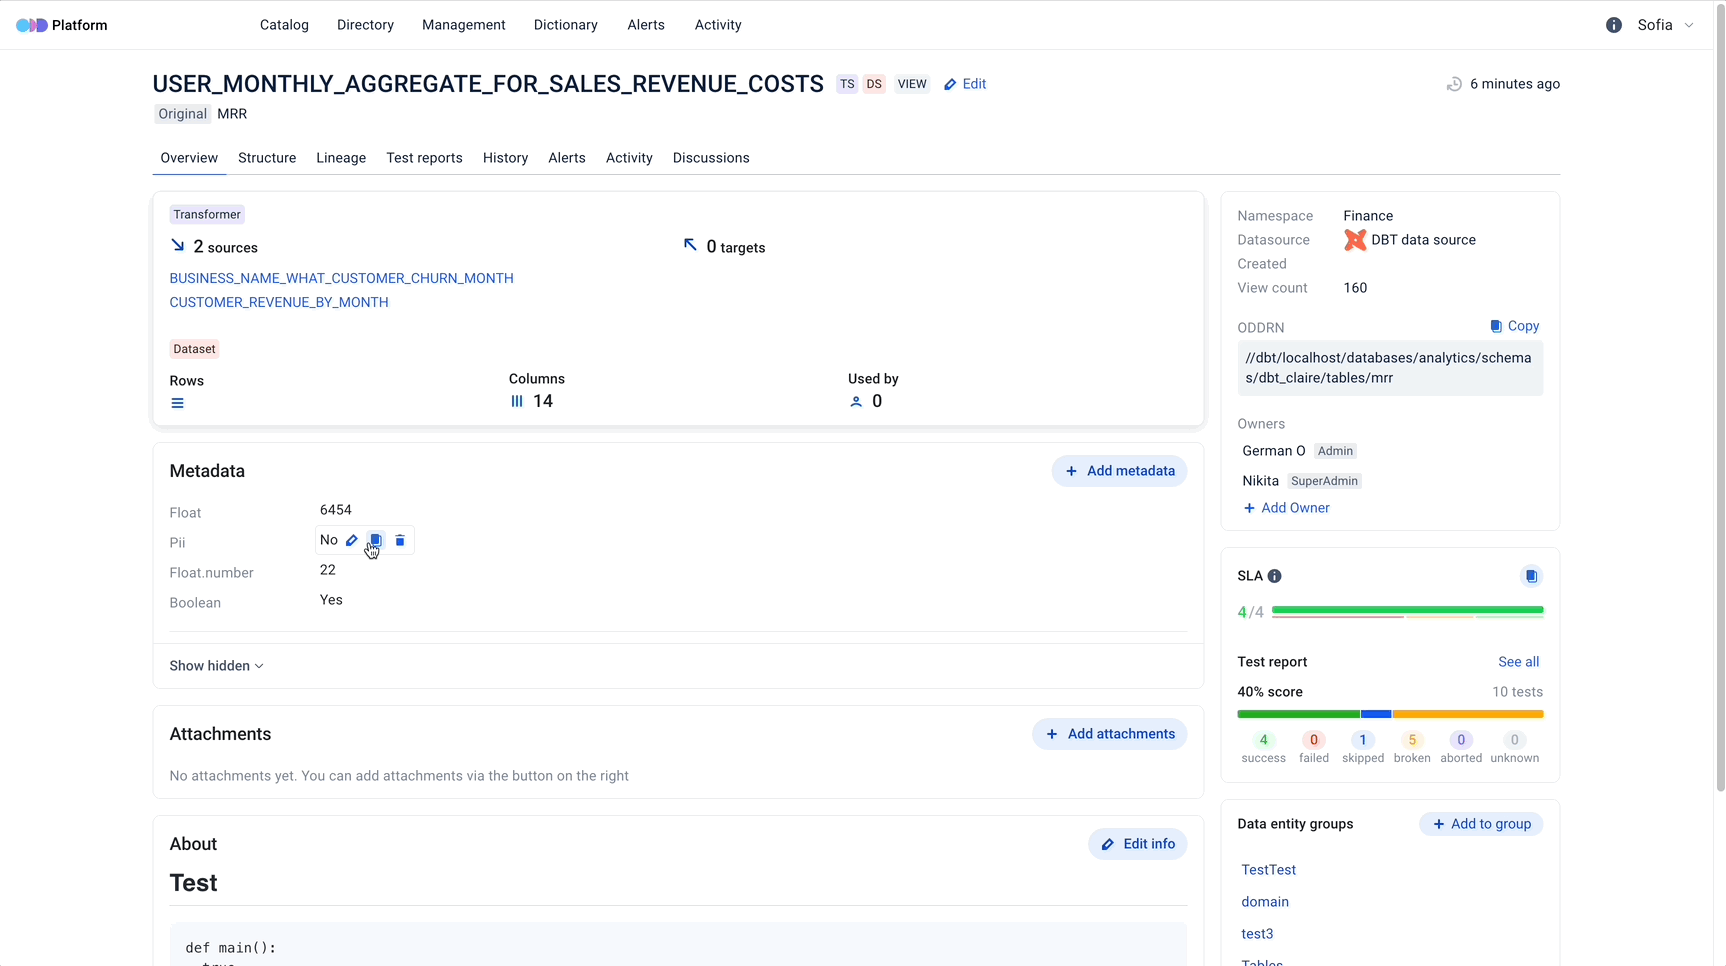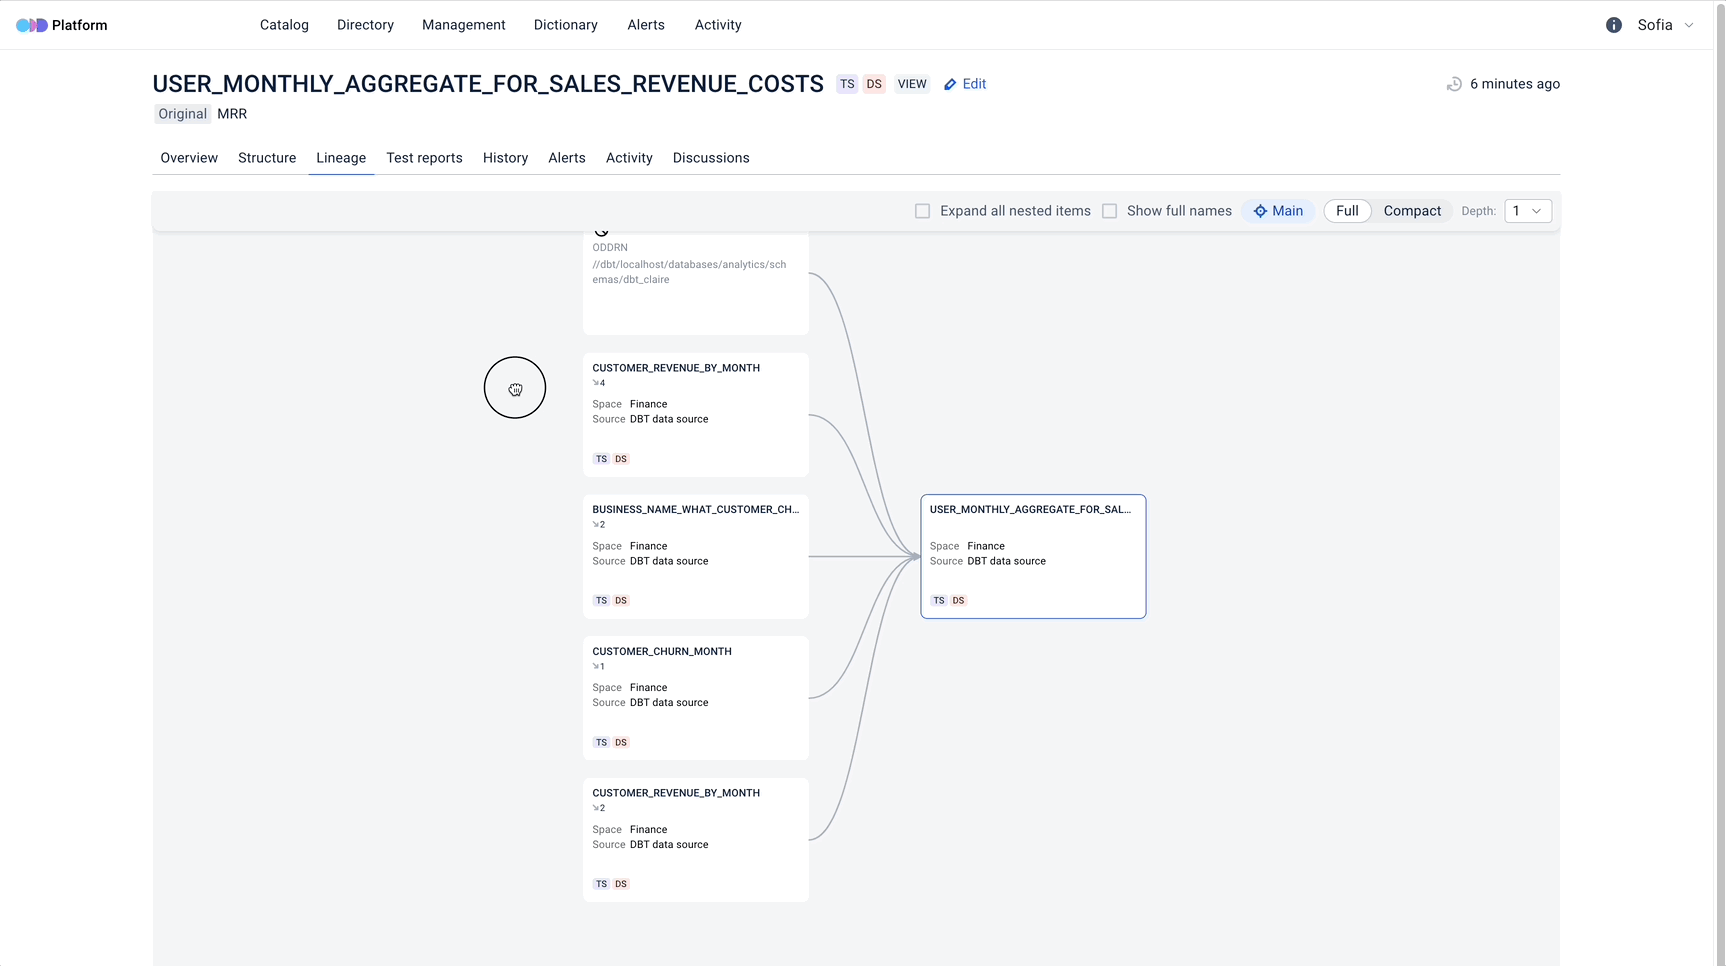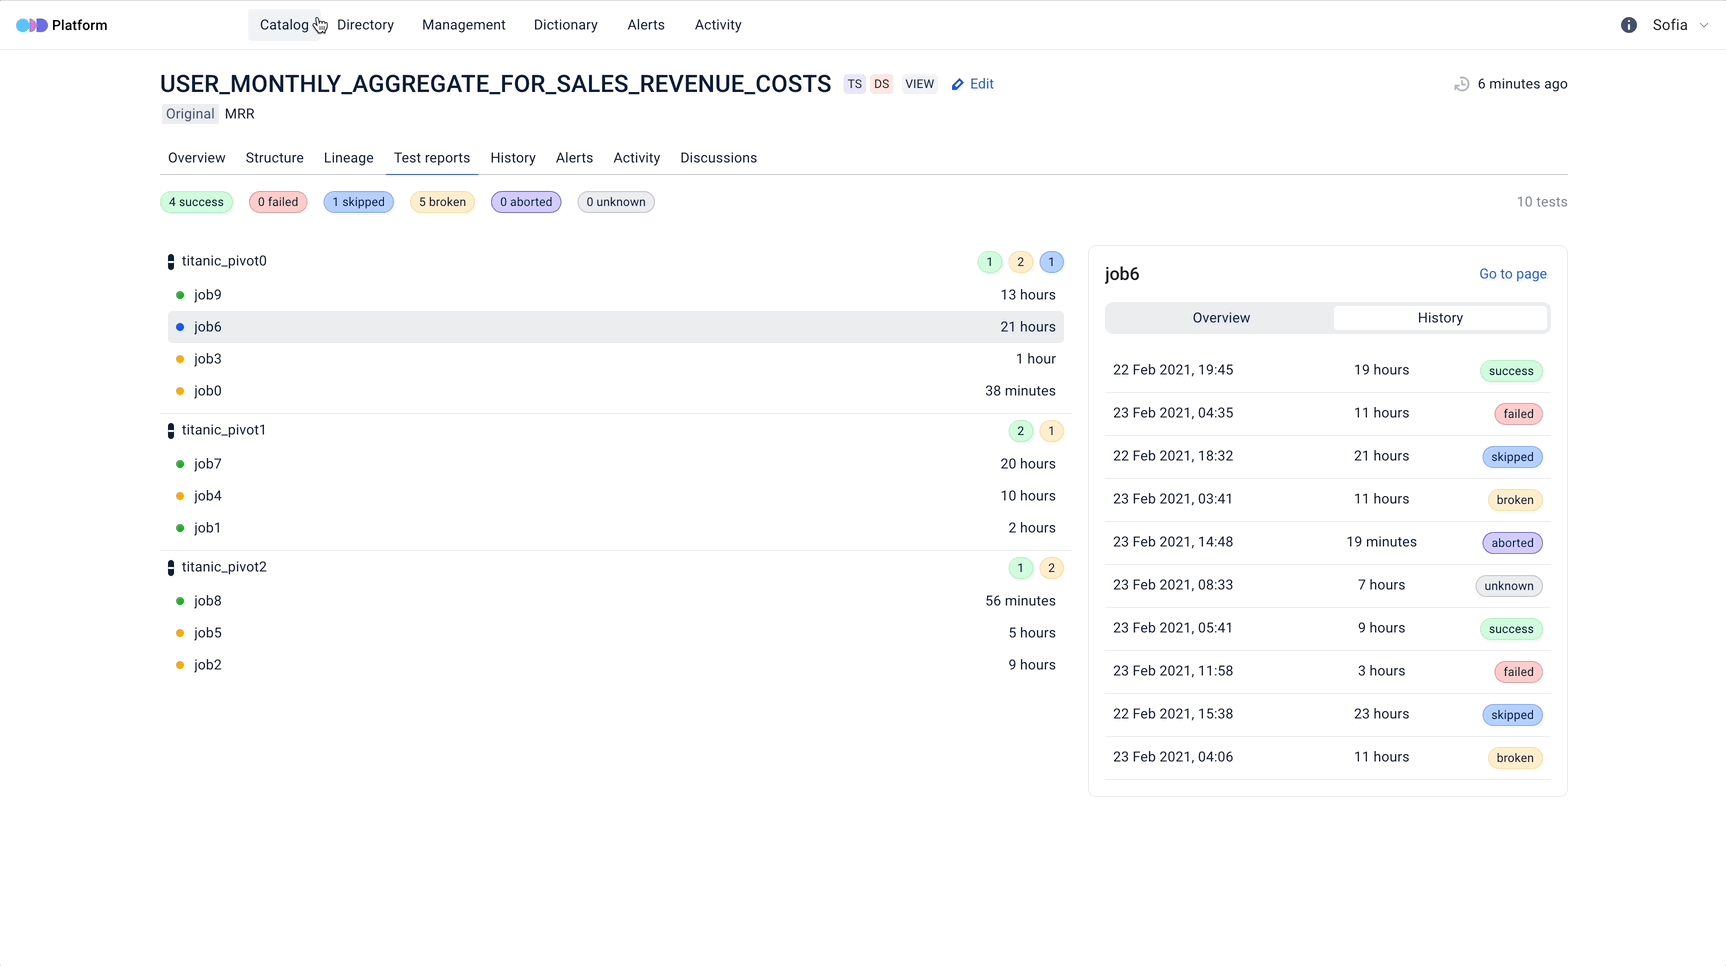
Demo
Play with our demo app!
Introduction
ODD is an open-source data discovery and observability tool for data teams that helps to efficiently democratise data, power collaboration and reduce time on data discovery through modern user-friendly environment.
Key wins
- Shorten data discovery phase
- Have transparency on how and by whom the data is used
- Foster data culture by continuous compliance and data quality monitoring
- Accelerate data insights
- Know the sources of your dashboards and ad hoc reports
- Deprecate outdated objects responsibly by assessing and mitigating the risks
- :point_right: ODD Platform is a reference implementation of Open Data Discovery Spec
Features
Data Discovery and Observability
- Accumulate scattered data insights in Federated Data catalogue
- Gain observability through E2E Data objects Lineage
- Benefit from cutting-edge E2E microservices Lineage feature in tracking your data flow through the whole data landscape
- Be warned and alerted by Pipeline Monitoring tools
- Store your metadata
- Use ODD-native modern lightweight UI
ML First citizen
- Save results of your ML Experiments by automatically logging its parameters
Data Security & Compliance
- Manage Tags to prevent any abuse of the data
- Refer to Tags to stay compliant with data security standards
- Have full transparency on how and by whom the data is used
Data Quality
- Utilize advanced Data Quality Dashboard to gain insights into data quality metrics, trends, and issues across your datasets, enabling proactive data quality management
- Simplify DQ processes by using ODD with Great Expectations and DBT tests compatibility
- Integrate ODD with any custom DQ framework
Reference Data Management (Lookup Tables) - a part of Master Data Management (MDM)
- Manage and store reference data centrally, ensuring a single source of truth for key data elements like currency codes, country names, and product categories, etc.
- Easily integrate Lookup Tables with data pipelines and transformations, enhancing data enrichment and validation processes
- Support data governance and compliance efforts by maintaining accurate and consistent reference data across all data assets
Getting Started
Running as a separate container
Setting up PostgreSQL connection details, for example:
export POSTGRES_HOST=172.17.0.1
export POSTGRES_PORT=5432
export POSTGRES_DATABASE=postgres
export POSTGRES_USER=postgres
export POSTGRES_PASSWORD=mysecretpassword
Starting new instance of the platform:
docker run -d \
  --name odd-platform \
  -e SPRING_DATASOURCE_URL=jdbc:postgresql://${POSTGRES_HOST}:${POSTGRES_PORT}/${POSTGRES_DATABASE} \
  -e SPRING_DATASOURCE_USERNAME=${POSTGRES_USER} \
  -e SPRING_DATASOURCE_PASSWORD=${POSTGRES_PASSWORD} \
  -p 8080:8080 \
  ghcr.io/opendatadiscovery/odd-platform:latest
Go to localhost:8080 in case of local environment.
Running Locally with Docker Compose
docker-compose -f docker/demo.yaml up -d odd-platform-enricher
Deploying to Kubernetes with Helm Charts
Example configurations
There are various example configurations (via docker-compose) within docker/examples directory.
Contributing
Contributing to ODD Platform is very welcome. For basic contributions, all you need is being comfortable with GitHub and Git. The best ways to contribute are:
- Work on new adapters
- Work on documentation
To ensure equal and positive communication, we adhere to our Code of Conduct. Before starting any interactions with this repository, please read it and make sure to follow.
Please before contributing check out our Contributing Guide and issues labeled “good first issue”:

Integrations
OpenDataDiscovery Platform offers comprehensive data source support to meet your needs.
ODD Data Model
ODD operates the following high-level types of entities:
- Datasets (collections of data: tables, topics, files, feature groups)
- Transformers (transformers of data: ETL or ML training jobs, experiments)
- Data Consumers (data consumers: ML models or BI dashboards)
- Data Quality Tests (data quality tests for datasets)
- Data Inputs (sources of data)
- Transformer Runs (executions of ETL or ML training jobs)
- Quality Test Runs executions of data quality tests
For more information, please check specification.md.
Join our community if you need help, want to chat or have any other questions for us:
- GitHub - Discussion forums and issues
- Slack - Join the conversation! Get all the latest updates and chat to the devs
If you have any questions or ideas, please don’t hesitate to drop a line to any of us.
License
ODD Platform uses the Apache 2.0 License.


评论