DeepWriting
Code for DeepWriting: Making Digital Ink Editable via Deep Generative Modeling paper.
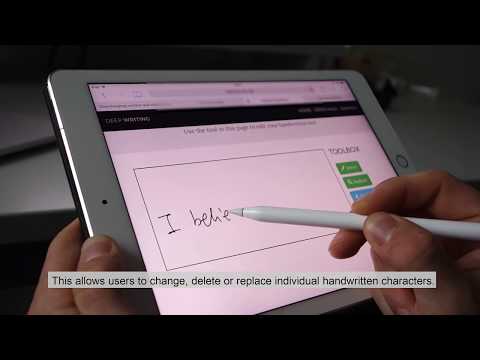
Implementation of conditional variational RNNs (C-VRNN) fow handwriting synthesis, generation, beautification and editing tasks.
Dataset
(November 2021) We released json files includeing timestamp information and stroke-based segmentations.
We collected data from 94 authors by using IAMOnDB corpus. After discarding noisy samples of IAMOnDB, we compiled a dataset of 294 authors, fully segmented. You can download our preprocessed data. For the raw dataset, license and other information, please visit our project page.
The dataset is in compressed .npz format. Strokes, labels and statistics can be accessed by using <key, value> pairs. We split handwriting samples by end-of-characters such that each sample consists of ~300 strokes. Samples are then moved to the origin and represented by using the offset values between consecutive strokes.
For example, you can visualize validation samples with indices 1, 5 and 20 by running
python visualize_hw.py -D ./data/deepwriting_validation.npz -O ./data_images -S 1 5 20
If you use our data, we kindly ask you to cite our work, and also fill IAMOnDB’s registration form and follow their citation requirements since our dataset extends IAMOnDB.
Training Model
- Training details and hyper-parameters are defined in
config.py.
- Download training dataset and copy into
data folder. Otherwise, don’t forget to update training_data and validation_data entries in config.py.
- Set
PYTHONPATH to include source.
export PYTHONPATH=$PYTHONPATH:./source
- Run training
python tf_train_hw.py -S <path_to_save_experiment>
- If you want to continue training
python tf_train_hw.py -S <path_to_save_experiment> -M <model_folder_name>
Evaluating Model
- You can either train a model or download our pretrained model.
- You can run
python tf_evaluate_hw.py -S <path_to_save_experiment> -M <model_folder_name> -QL
- Evaluation options are defined in
tf_evaluate_hw.py globally.
Dependencies
- numpy
- Tensorflow 1.2+ (not sure if earlier versions work.)
- matplotlib
- OpenCV (pip install opencv-python is enough)
- svgwrite
- scikit
- sklearn
Missing
We are not planning to release demo interface.
Citation
If you use this code or dataset in your research, please cite us as follows:
@inproceedings{Aksan:2018:DeepWriting,
	author = {Aksan, Emre and Pece, Fabrizio and Hilliges, Otmar},
	title = {{DeepWriting: Making Digital Ink Editable via Deep Generative Modeling}},
	booktitle = {SIGCHI Conference on Human Factors in Computing Systems},
	series = {CHI '18},
	year = {2018},
	location = {Montr{\'}eal, Canada},
	publisher = {ACM},
	address = {New York, NY, USA},
}


评论