DeepSeek-OCR-2-Unlimited-OCR is an advanced, experimental visual document processing and open-ended text localization dashboard. This application establishes a unified interface that allows users to swap between two premier vision-language document models: deepseek-ai/DeepSeek-OCR-2 and baidu/Unlimited-OCR.
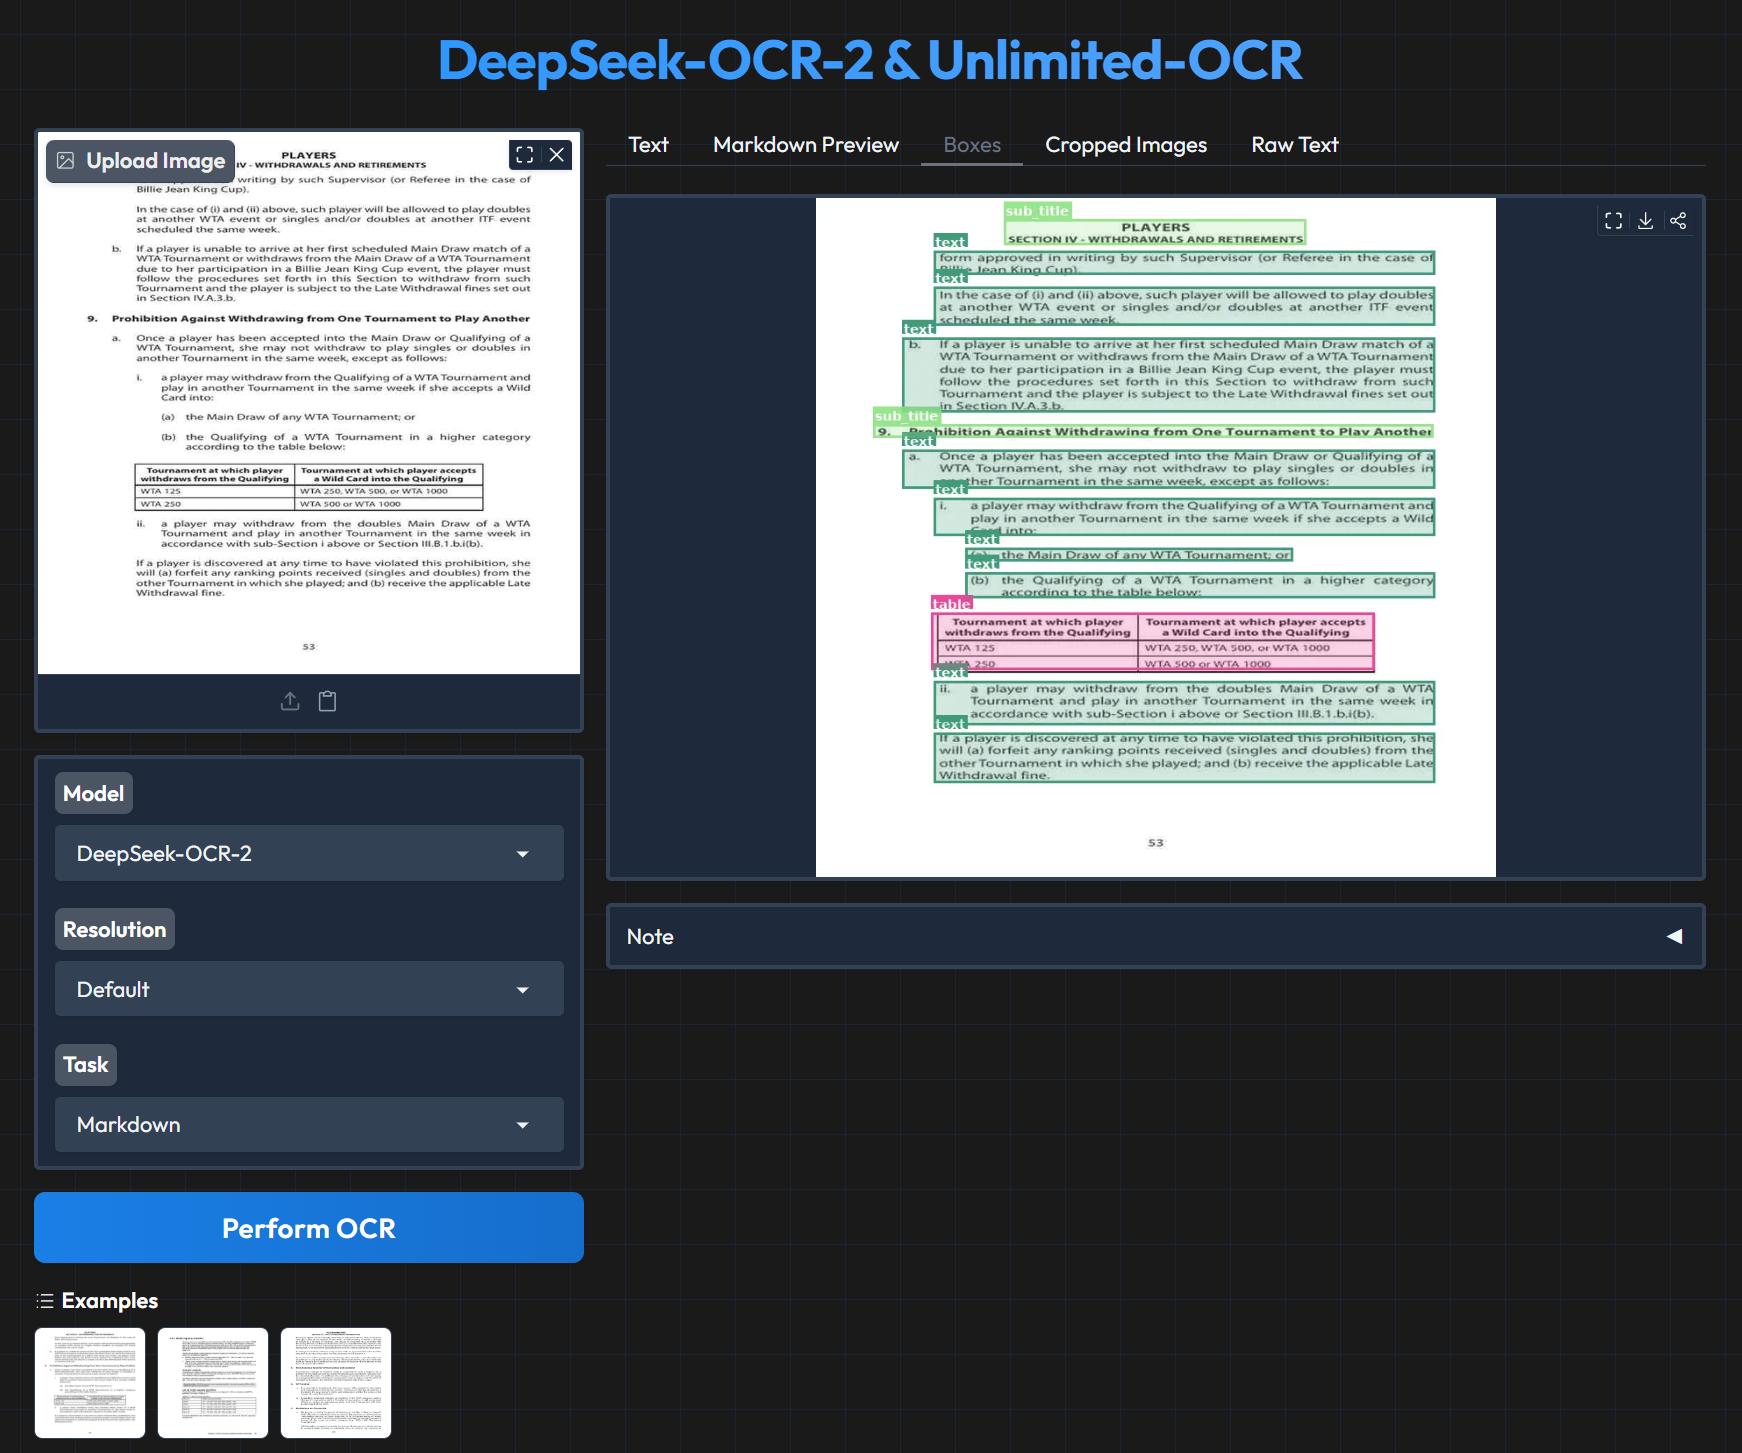
The core system handles document-to-markdown conversion, mathematical layout rendering, dense object localization, and raw textual extraction. Crucially, the platform leverages structured parsing loops to capture coordinate boundaries (<|ref|> and <|det|>), dynamically painting multi-colored bounding boxes directly on the document while segmenting and extracting sub-figure graphics into a standalone output gallery. Fully optimized via specialized Flash Attention 2 layers, the app operates as a localized, high-speed vision suite tailored for complex multi-lingual document intelligence.
| example 1 |
example 2 |
 |
 |
Key Features
- Dual-Backbone Document Intelligence: Seamlessly switch between the highly structural
DeepSeek-OCR-2 architecture (optimized with Flash Attention 2) and the long-context Unlimited-OCR model capable of matching up to 32,768 tokens.
- Granular Visual Grounding: Programmatically maps detected text lines, headings, and embedded graphics into precise spatial bounding boxes.
- Sub-Figure Graphic Cropping: Automatically captures figure bounding boxes, crops target graphics from the primary source image canvas, and populates them into an interactive Gradio thumbnail gallery.
- Adaptive Aspect Resolution Profiles: Offers multi-stage processing configs (e.g., Default, Quality, Fast, No Crop, Gundam) to scale internal dimensions up to $1536^2$ while handling aspect ratios smoothly.
- Bespoke Dodger Blue UI Architecture: Enclosed inside a tailored, web-responsive blueprint featuring a grid backdrop, explicit multiline code blocks, dedicated Markdown layout previews, and full layout state synchronization.
Repository Structure
├── demo-notebook/
│   └── DeepSeek_OCR_2_Demo.ipynb
├── examples/
│   ├── 1.jpg
│   ├── 2.jpg
│   └── 3.jpg
├── deepseek_ocr_2_unlimited_ocr.py
├── LICENSE.txt
├── pre-requirements.txt
├── README.md
└── requirements.txt
Installation and Requirements
To initialize the DeepSeek-OCR-2-Unlimited-OCR suite locally, configure a Python 3.10 environment with the exact deep learning stack specified below. A local system containing a dedicated CUDA cu12-enabled GPU is required.
1. Upgrade Package Manager
Update your system package installer before fetching modern pre-compiled wheel distributions:
pip install pip>=26.0.0
2. Install Core Stack
Install the explicit PyTorch 2.8.0 and CUDA cu12 dependencies, alongside specialized Flash Attention 2 binaries. Place these inside a requirements.txt file and run:
pip install -r requirements.txt
Core Requirements List (requirements.txt)
flash-attn @ https://huggingface.co/strangertoolshf/flash_attention_2_wheelhouse/resolve/main/wheelhouse-flash_attn-2.8.3/linux_x86_64/torch2.8/cu12/abiFALSE/cp310/flash_attn-2.8.3+cu12torch2.8cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
git+https://github.com/huggingface/[email protected]
git+https://github.com/huggingface/accelerate.git
git+https://github.com/huggingface/diffusers.git
git+https://github.com/huggingface/peft.git
tokenizers==0.20.3
huggingface_hub
sentencepiece
torch==2.8.0
torchvision
matplotlib
accelerate
easydict
addict
gradio==6.9.0
einops
spaces
numpy
Usage
Once your compiled infrastructure wheels and underlying tokenizer layers have successfully loaded, launch the script locally:
python deepseek_ocr_2_unlimited_ocr.py
Upon initialization, the system pre-loads the default model weights into device VRAM. Open your web browser to the local network link (typically http://127.0.0.1:7860/).
- Upload Asset: Drop an image document, textbook page, invoice, or diagram into the Upload Image zone (supports direct clipboard pasting).
- Configure Pipeline: Select your target Model backbone, adjust the Resolution profile, and pick an operational task:
- Markdown: Converts layout formats directly to standard Markdown, embedding tables, formulas, and structural text.
- OCR Image / Free OCR: Extracts pure textual elements line by line.
- Locate: Enter custom words inside the prompt line to programmatically locate text positions.
- Execute: Click Perform OCR. Each model is lazy-loaded on its first selection and cached subsequently on the GPU. Explore the generated data across the dedicated Text, Markdown Preview, Boxes, Cropped Images, and Raw Text tab layouts.
License and Source


评论