Canonry The agent-first AEO operating platform. Track mentions and citations across ChatGPT, Claude, Gemini, Meta Muse, and more. Join them with Search Console, GA4, ads, AI crawler traffic, site audits, and SEO data. Then let your agent create content, publish fixes, manage ChatGPT ads, get pages indexed, and measure what changed. Open source · Self-hosted · Bring your own keys Try the live demo · Quick…
The agent-first AEO operating platform.
Track mentions and citations across ChatGPT, Claude, Gemini, Meta Muse, and more. Join them with Search Console, GA4, ads, AI crawler traffic, site audits, and SEO data. Then let your agent create content, publish fixes, manage ChatGPT ads, get pages indexed, and measure what changed. Open source · Self-hosted · Bring your own keys
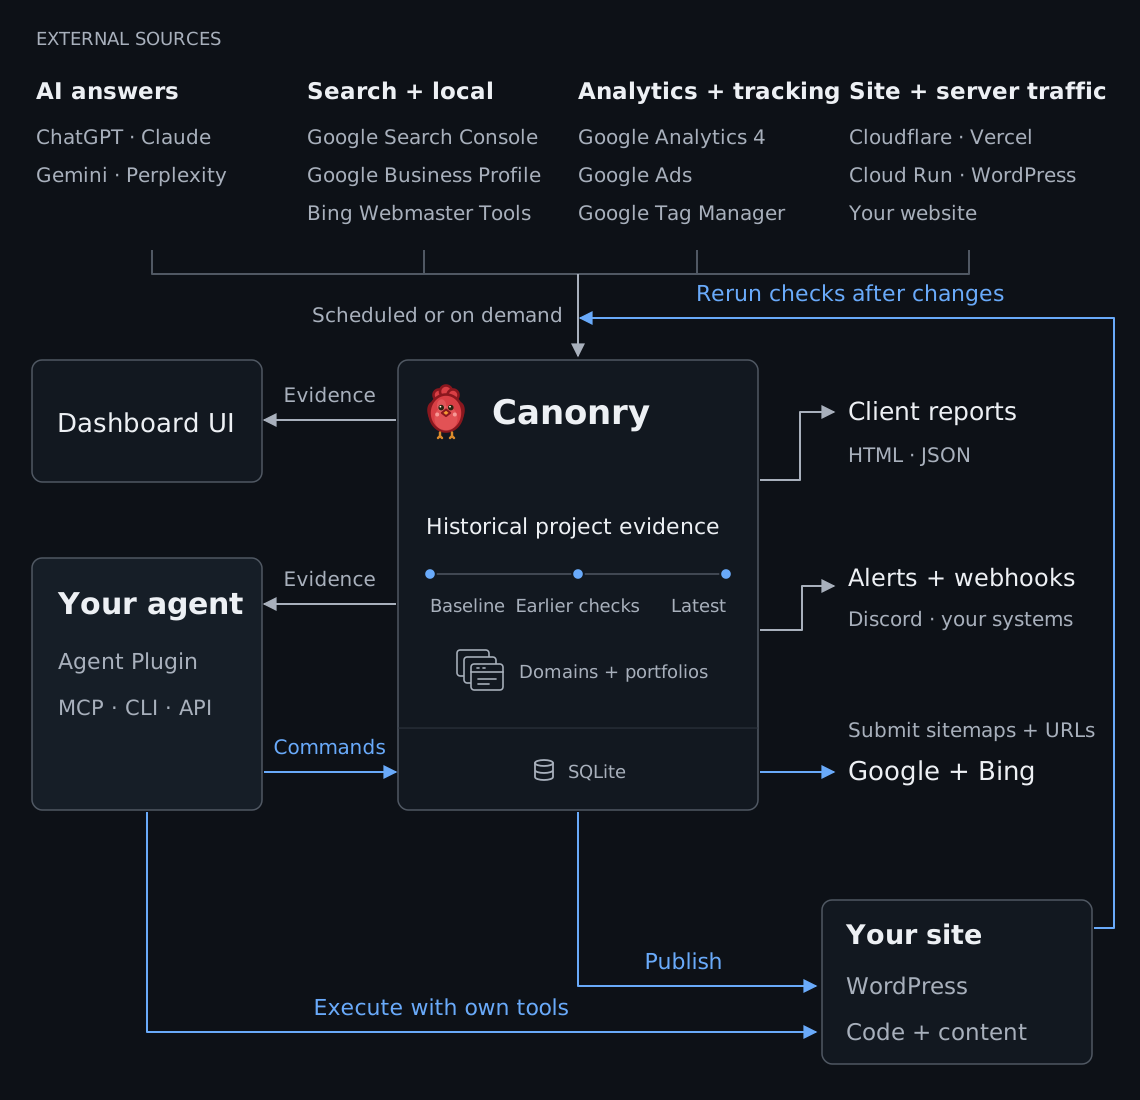
Everything runs on one REST API. The dashboard, CLI, MCP server, and plugins all call it, so your agent can read and do everything you see.
REST API: every dashboard number has a typed endpoint under /api/v1. The full OpenAPI spec is at GET /api/v1/openapi.json. API →
CLI: the same calls as cnry <command> --format json, for scripts and shell agents. CLI →
MCP and plugins: plugins for Claude Code and Codex, or a hosted MCP server for ChatGPT and Claude Desktop. MCP → · Plugin →
AI Visibility
Track brand mentions and citations by query and answer engine. See where competitors win, then open the exact answer and sources behind each result. Docs →
Server-Side AI Traffic
See what AI agents actually do on your site, from your server logs: which pages GPTBot, ClaudeBot, Meta AI, and Grok crawl, which pages ChatGPT, Claude, and Meta AI open for users, and who clicks through. Docs →
Site Health
Crawl your site, score each page for AI readiness, and map the internal links between pages. Each finding lists the pages it affects. Docs →
SEO Research
Keyword volume, difficulty, organic rankings, and search gaps against competitors, powered by DataForSEO Labs. Docs →
Ads
Let your agent run ChatGPT Ads: sync campaigns and daily results, create and edit campaigns, and switch them on only after you approve. Track Google Ads spend and conversions, and check each conversion’s setup across Google Ads and Tag Manager. Paid results stay separate from organic mentions and citations. ChatGPT Ads → · Google Ads →
Also in the box:
Aero — A built-in analyst in the dashboard that reads your evidence and explains what changed.
Portfolios — Versioned measurement plans for locations, products, or site sections. Branded and non-brand queries stay separate.
Competitor landscape — Mention share, mentions, and citations for you and your competitors over time.
Query discovery and research — Find new queries to track, or run one-off research without changing what you track.
Content engine — Finds content gaps and the pages to write or improve next, so your agent can draft them and publish to WordPress for review.
Publish and index — WordPress drafts, JSON-LD, and sitemap and URL submissions to Google and Bing.
Schedules and webhooks — Rerun checks on a schedule and send alerts to Discord, Slack, or your systems.
Backlinks — Common Crawl link data, queried locally with DuckDB.
Sentiment — Experimental, off by default. Rates branded answers as favorable, mixed, or unfavorable.
Find where competitors get cited and we don’t. Use search data and the site audit to prepare a pull request or WordPress draft for review. After it ships, rerun checks and report what changed.
How it works
Supported Engines
Compare direct AI engines, OpenRouter models, and search answers from Exa and Parallel. Each keeps its own results and history.
Paste this into Claude Code, Codex, or any shell-capable coding agent.
Copy the first-time setup request
Help me set up Canonry for my public site.

Use the official Canonry docs:
- Agent quickstart: https://github.com/Canonry/canonry#or-use-any-shell-capable-coding-agent
- CLI reference: https://github.com/Canonry/canonry/blob/main/skills/canonry/references/canonry-cli.md
- Plugin setup: https://github.com/Canonry/canonry/blob/main/docs/plugins.md
- MCP setup: https://github.com/Canonry/canonry/blob/main/docs/mcp.md

Pick one path and stay on it. Use connected Canonry tools (plugin or MCP) only if you have them and I have not pointed you at a specific install. A connected tool runs in its own process and never sees `CANONRY_CONFIG_DIR`, `CANONRY_PORT`, or anything else you export in a shell, so it always acts on my default install. If I named a config directory, a port, or a sandbox, that is the shell path: use `cnry` and tell me which path you chose. Never mix the two in one run, and never create a duplicate project. The `cnry` and `canonry` commands are interchangeable.

1. Ask for my public domain, country, and language. Do not create or scan anything yet. Country and language are only applied when a project is created, so if you reuse an existing project, report its country and language instead of changing them.
2. Shell path only: confirm `cnry` is on PATH, then run `cnry --version`. If Canonry is missing, propose `npm install -g @canonry/canonry` and wait for approval. Then run `cnry doctor --format json`, which is the command that says whether config, database, and server are in place. `cnry --version` does not read config and succeeds on a completely unconfigured install, so it cannot answer this. If config is missing, run `cnry bootstrap` yourself: it is not interactive, takes about a second, and is safe to rerun. Do not hand it to me and wait. The interactive command is `cnry init`, which is optional provider and OAuth setup that Page Health does not need. Bootstrap prints an API key, so do not repeat its output back to me, and never ask me to paste passwords, API keys, OAuth credentials, or command output.
3. Confirm the API is reachable. `cnry doctor --format json` reports it, and any project read exits non-zero with `CONNECTION_ERROR` when it is not. If it is unreachable, propose `cnry start` and wait for approval. Use `cnry start`, which is the background daemon, and not `cnry serve`, which runs in the foreground and will block you until I stop it, even though some error messages suggest it. Stop anything you started with `cnry stop`.
4. List projects with the connected project tool or `cnry project list --format json`, and reuse one whose domain matches. Confirm the proposed name is not already assigned to a different domain. To find out whether a project has already been scanned, run `cnry technical-aeo score <project> --format json` with no `--run-id`, which reports the latest run. Read the `hasData` field, not the score: this command exits 0 and reports `aggregateScore: 0` for a project that has never been scanned, so reading the score alone would have you tell me my site scored zero. If `hasData` is true and `runStatus` is `completed` or `partial`, read that scan instead of starting a new one. If no project matches, show the exact create operation and wait for approval.
5. Propose a bounded Site Health scan: `--max-pages 100` for a first look, plus whether dead-link checking is on (it is off unless you pass `--check-dead-links`). Show the connected operation or the exact `cnry technical-aeo run <project> --max-pages 100 --wait --format json` command with the project name filled in, and wait for separate approval before scanning. `--wait` polls for up to 15 minutes and returns only the run id and status. If the status it returns is still `queued` or `running`, the scan has not finished: do not rerun it or report results, poll `cnry technical-aeo progress <project> --run-id <run-id> --format json` until it is terminal. If `--wait` outruns your own tool timeout first, recover the run id with `cnry technical-aeo score <project> --format json` and poll the same way.
6. When the run is `completed` or `partial`, read `cnry technical-aeo crawl <project> --run-id <run-id> --format json` first. It is the only one of these commands that carries `termination` and `complete`; the score and pages commands do not. Then read `cnry technical-aeo score <project> --run-id <run-id> --format json` and `cnry technical-aeo pages <project> --run-id <run-id> --sort score-asc --limit 10 --format jsonl`. Tell me the termination reason in plain words and whether the scan covered the whole site or stopped at a page, link, depth, or time limit. A `partial` run scored the pages it reached and not my site, so never present it as a full-site result. If it stopped early, the fix depends on the reason, so say which: a page or depth limit needs a larger budget, a time limit needs a smaller scan (a lower `--max-pages` or `--max-depth`). If the run failed or was cancelled, inspect the run error and stop.
7. Summarize only compl

提示:代码过长已自动截断
With the plugin
# Claude Code
claude plugin marketplace add Canonry/canonry
claude plugin install canonry@canonry

# Codex
codex plugin marketplace add Canonry/canonry
codex plugin add canonry@canonry
Then open http://127.0.0.1:4100/setup and follow the setup to scan your site. The crawl saves a Page Health baseline. AI Visibility is optional and has a separate setup.
Scan and read results from the terminal
Keep cnry serve active. In a second terminal, create a project and start a bounded scan:
cnry project create my-site --domain example.com --country US --language en
cnry technical-aeo run my-site --max-pages 100 --wait --format json
Read the run ID and status from the output. If the status is completed or partial, read evidence from that run:
--wait polls for up to 15 minutes. If the scan remains active, use cnry technical-aeo progress <project> --run-id <id> --format json.
If the scan fails or is cancelled, read the error with cnry run show <run-id> --format json.
Configure a provider and run visibility checks
For an existing project, configure a provider with your own key.
cnry query add my-site "your first query" "your second query"
cnry run my-site --wait
cnry visibility-stats my-site --by-provider
Direct APIs, OpenRouter, and search answer services
Canonry supports direct model APIs, OpenRouter, and search answer services such
as Exa and Parallel. Direct adapters retain the search and grounding details
each provider exposes. OpenRouter offers multiple models through one key. Exa
and Parallel search the web and return answers with source evidence.
Each direct engine, OpenRouter model route, and service profile keeps separate
results and history. The same model through different APIs can return different
answers and citation evidence. Canonry measures brand mentions separately from
source citations and keeps missing evidence unknown.
Provider guides describe the evidence and limits of
each integration.
Discover questions or run one-off research
Expand your tracked questions. Run cnry discover run <project> --icp "...". This does not change the tracked questions.
Preview a completed session with cnry discover promote preview <project> <session-id>. Promote only after approval.
Research without changing tracking. Run cnry research run <project> "query one" "query two" --wait.
For a configured portfolio destination, select one --market <key> or --property <key>; Canonry saves the destination with the answers without changing the query. Add paired --template-id <id> --template-version <version> only to preserve an already-expanded template’s provenance. Research never adds queries to the tracked questions.
Troubleshoot installation, scans, and visibility results
Canonry is single-tenant. Run one instance for one operator or team. Keep unrelated teams on separate instances.
The CLI and REST API are the primary interfaces. They expose measurements, diagnoses, actions, evidence exports, and schedules.
OpenAPI is available at GET /api/v1/openapi.json.
See the deployment guide for reverse proxies, daemon mode, Docker, systemd, and Tailscale.
git clone https://github.com/Canonry/canonry.git && cd canonry
pnpm install
For local agent work, run tests only after changes are finalized and ready for push or review.
pnpm verify is optional locally. See CONTRIBUTING.md and the testing guide.
License
MIT, starting with Canonry 5.0.0. Use, modify, self-host, redistribute, and build commercial products with Canonry. Keep the copyright and permission notice with copies or substantial portions of the software.
Earlier releases retain their original licenses, including any future-license grants. Dependencies and bundled assets retain their own licenses; see third-party notices.


评论